
Before this unit: Image formation
The Camera Matrix: K, [R|t] and P, Worked on a Real Chessboard
Lesson 2 of Camera Geometry. A camera is one 3×4 matrix: the focal lengths and image centre in K, where the camera stands in [R|t], and their product P, which sends any point of the world to a pixel. Worked on one corner of a chessboard in OpenCV's own calibration photos, checked against cv2.projectPoints, and taken apart again.
The camera matrix is a single table of twelve numbers that sends any point of the world to the pixel where a camera sees it. Below, a cube that does not exist is drawn standing on a real chessboard in each of thirteen photographs, through the camera matrix of each photo.
You have met it wherever software draws into a camera’s view:
- Augmented reality draws virtual furniture, labels and game pieces through the phone camera’s matrix, recomputed every frame as the phone moves.
- Sports broadcasts draw the first-down line or the offside line through the matrix of the broadcast camera.
- 3-D games and graphics use the same matrix, under the name “view and projection”, to draw the world on the screen.
cv2.projectPoints, the OpenCV call this lesson rebuilds.
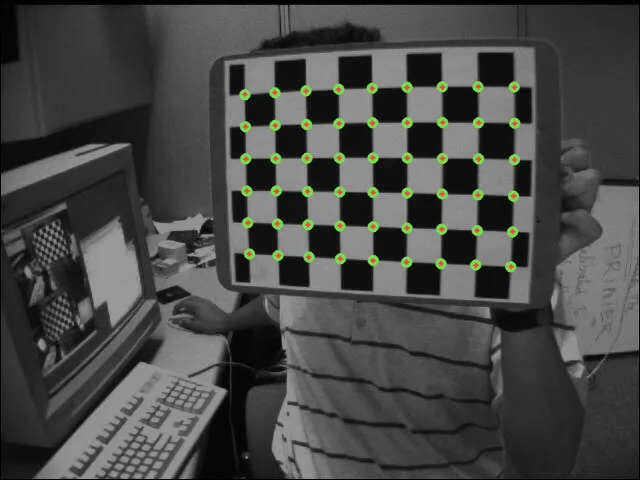
A camera is one 3×4 matrix: three numbers say where it stands, three which way it faces, and five who it is, and multiplying a point by it gives the pixel. On the first of OpenCV’s calibration photos it puts a board corner at (523.98, 77.94); with the lens added, 0.34 px from where the detector found it.
Where we are
Lesson 2 of camera geometry, and steps 2 to 5 of its pipeline: move a point into the camera’s frame, divide by its depth, and turn the result into pixels. Lesson 1 gave points an extra coordinate so that the division becomes part of a matrix product. Unit 1.1 wrote the pinhole as two equations for a point already in the camera’s frame; here the point starts on a chessboard, and the camera has to be placed first.
Who the camera is: K
The pinhole equations of unit 1.1 use four numbers that belong to the camera and not to the photo: the focal length in pixels along each axis, and , and the image centre . Written as a matrix acting on a point in the camera’s frame, they are
where , the skew, is zero for every modern sensor. Multiplying a camera-frame point by gives , and dividing by the last entry gives the two pinhole equations back [1] [2]. For OpenCV’s sample camera, calibrated in lesson 3:
A focal length of 536 px on a 640 px wide sensor is a horizontal field of view of .
Where it stands: [R | t]
The board’s corners are known in the board’s own frame, one unit per square. To use the point has to be in the camera’s frame first: rotated by , a 3×3 rotation, and shifted by . For the first photo, from calibration:
is a turn of about 18.5°, and is where the board’s first corner sits in front of the camera: three squares left, four up and sixteen ahead. The camera’s own position on the board is squares, 16.85 squares from the board’s first corner.
The whole camera: P = K [R | t]
Stacking and side by side gives a 3×4 matrix that moves a point written as , and multiplying by gives the whole camera in one matrix, :
Now you try
A scene and the pinhole view of it, side by side. Push the ball away from the camera and watch its projected size fall by the same factor its distance grew; change the focal length and watch the field of view narrow. (The lab draws up, so lifting the ball makes smaller.)
How close is this to OpenCV?
cv2.projectPoints takes the pose as a rotation vector and a shift, builds the same product
and applies the lens [3]. The cells build by hand from the numbers above, then
compare, then take apart again with cv2.decomposeProjectionMatrix.
import numpy as np

# who the camera is: focal lengths and centre, in pixels
K = np.array([[536.0735, 0, 342.3705],
              [0, 536.0164, 235.5369],
              [0, 0, 1]])
# where it stands for the first photo: rotation, shift
R = np.array([[0.962221, 0.009801, 0.272095],
              [0.036270, 0.985831, -0.163771],
              [-0.269845, 0.167453, 0.948232]])
t = np.array([-3.011188, -4.357567, 15.992873])

P = K @ np.hstack([R, t[:, None]])  # the whole camera
X = np.array([8, 0, 0, 1.0])        # a board corner
u, v, w = P @ X
print("P @ X =", np.round([u, v, w], 3))
print(f"pixel: ({u / w:.2f}, {v / w:.2f})")P @ X = [7248.744 1078.247 13.834] pixel: (523.98, 77.94)
import cv2

rvec, _ = cv2.Rodrigues(R)
pt = X[None, :3]
p, _ = cv2.projectPoints(pt, rvec, t, K, None)
print("cv2.projectPoints:", p.ravel().round(2))

dist = np.array([-0.26509, -0.04674, 0.00183,
                 -0.00031, 0.25231])
q, _ = cv2.projectPoints(pt, rvec, t, K, dist)
print("with the lens:", q.ravel().round(2),
      " detected: [513.77  86.53]")

# and back: take P apart again
Kd, Rd, Ch = cv2.decomposeProjectionMatrix(P)[:3]
print("K back:", (Kd / Kd[2, 2]).diagonal().round(2))
print("camera centre:", (Ch[:3] / Ch[3]).ravel().round(3))cv2.projectPoints: [523.98 77.94] with the lens: [514.05 86.72] detected: [513.77 86.53] K back: [536.07 536.02 1. ] camera centre: [ 7.371 1.647 -15.059]
OpenCV returns the same pixel to the hundredth, and the lens moves it to within 0.34 px of
the detection. decomposeProjectionMatrix recovers and the camera centre from alone,
which is the sense in which is the whole camera: nothing about it is missing.
On the other twelve photos
is the same for every photo and is not: the thirteen photos put the camera between 11.9 and 16.85 squares from the board’s first corner, at different angles. The cube in the opening animation is drawn through thirteen matrices that share their first 3×3 factor.
Where this breaks
The lens is not in the matrix. is a pinhole: without the lens coefficients the corner above is 13.3 px off, and the bend cannot be written as a matrix because it depends on the square of the distance from the centre. OpenCV applies it as a separate step between the division and .
One flat board does not fix . has eleven free numbers. A flat board in one photo gives a homography, eight, so it cannot tell a long lens far away from a short one close up on its own. Finding takes several photos of the board, which is lesson 3.
Exercises
- Through the matrix. Write
to_pixel(P, X), the pixel a 4-vector lands on under the camera matrixPfrom the cells above.
def to_pixel(P, X):
    return (0.0, 0.0)  # (u, v) for a point (X, Y, Z, W)

print(to_pixel(P, X))- Predict, then run. Push the board’s X axis at infinity, , through
P. Where does it land, and is that inside the 640×480 photo? - Where is the camera? Compute and its distance from the board’s first corner.
What you should see
These come from the “Lesson 2” cells of the unit notebook, camera_geometry.ipynb, and are
the same on OpenCV 4.11 (this page) and 5.0.
(523.98, 77.94)for the corner .- : far off the left edge. That is the vanishing point of the board’s rows, where all of them would meet.
- , 16.85 squares away.
Check yourself
Four questions on this lesson. Pick an answer to see why it is right or wrong.
What does K hold?
K is the same for every photo from that camera. Where the camera stands, [R | t], changes with each photo.
P (8, 0, 0, 1) = (7248.74, 1078.25, 13.834). What is the pixel?
Divide the first two entries by the third. That division by depth is the perspective.
The camera matrix alone puts the corner 13.3 px from where it was detected. Why?
The bend depends on the square of the distance from the centre, so it is applied as a separate step between the division and K.
Where is the camera on the board for the first photo?
t is the board’s origin seen from the camera; the camera seen from the board is −Rᵀ t. decomposeProjectionMatrix recovers it from P.
Next
was given here. Lesson 3 finds and the lens from thirteen photos of the board, and lesson 4 finds from one photo once is known.
References
[1] Hartley, R., & Zisserman, A. (2004). Multiple View Geometry in Computer Vision (2nd ed.), ch. 6 “Camera Models” (p. 153). Cambridge University Press.
[2] Szeliski, R. (2022). Computer Vision: Algorithms and Applications (2nd ed.), §2.1.4 “3D to 2D projections”. Springer. Free PDF
[3] OpenCV Documentation (5.0). Camera Calibration and 3D Reconstruction (calib3d): projectPoints, decomposeProjectionMatrix. docs.opencv.org/5.0