
Image Formation: How a Camera Flattens the World Onto a Sensor
How to predict where any point in the world lands in a photograph, and undo what the lens did on the way. One pipeline, from a point to its ray to the lens's bend to a pixel, with focus as a side question, measured on public photographs: a real lens moves a corner 51 px, and a fisheye fitted with the wrong model misses by 7.3 px against 0.64 px with the right one.
This unit is about predicting where any point in the world lands in a photograph, and undoing what the lens did to it on the way. The same model covers a phone’s main camera, its ultra-wide and a 180° fisheye once the lens’s curve is right, and it is what every measurement taken from a photo stands on. The animation shows the finished result: one photograph taken through a fisheye lens, re-rendered as the three cameras on the back of a phone.
Every lesson is one step of the path from a point in the world to a pixel, or a side question off it:
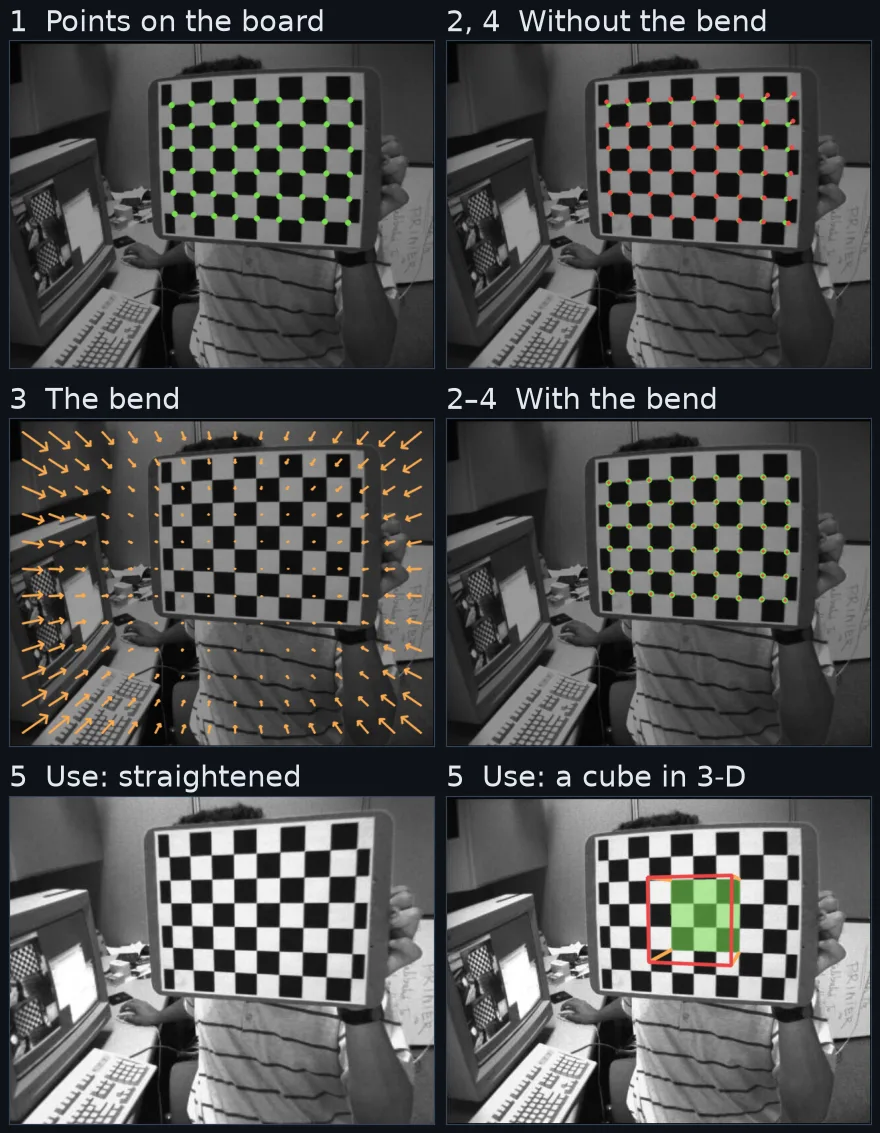
- A point in the world. Here a corner of a printed chessboard, at a known position on the board.
- Its ray. Light from the point travels in a straight line through the lens’s centre. Where it meets the sensor depends only on its direction, which is the point’s sideways position divided by its depth (lesson 1).
- The bend. Real glass bends rays more toward the edges of the frame than a pinhole would, pulling or pushing each point along the line from the centre (lesson 3); past about 120° of field the bend is the design and needs a different curve (lesson 4).
- Into pixels. Multiply by the focal length in pixels and add the image centre, which on a real camera is not the middle of the frame (lesson 1).
- Use it. Predict where something will appear, straighten a photo, or measure in it.
The focus question leaves at step 2: a lens gathers the light of each point into a sharp dot only at one distance, and into a disc everywhere else (lesson 2).
What the outputs are used for
You use this model every time you take a picture, and each use acts on the numbers it returns:
- Phone cameras switch between lenses of different focal length when you tap 0.5×, 1× or 3×; the focal length is step 4’s number, and it sets how much of the scene fits.
- Augmented reality draws a virtual object where the model says the floor or the marker is, as the cube in panel 6.
- Measuring from photos. Lines must be straight before a ruler or a homography can be laid on them: straightening a court camera’s lens cut a measurement error from 5.95 cm to 1.96 cm in unit 3.5.
- Action cameras, dashcams and security domes use very wide or fisheye lenses, and the software that flattens their footage runs step 3 backwards with the fisheye curve.
- Portrait mode imitates the shallow focus of a large lens that a phone does not have, by blurring what the focus branch says should be a disc.
A camera sends every point of the world along a straight ray to the sensor, and the lens then bends that ray by an amount you can measure and undo. On OpenCV’s own calibration photos the bend moves a corner of the frame by 51 px, and on a fisheye the wrong lens model misses by 7.3 px where the right one misses by 0.64 px.
Before this
Nothing. This is the first unit on the Fundamentals track and it assumes only that you have seen an image as an array of numbers.
What comes after it is image sensing, which follows the light past the lens and into the sensor, and then the image as data, which covers the array, its grid and its colour axes. After those come 2D convolution and edge detection, both of which assume the array in front of them came from a camera that behaves like the model below.
How to write down the camera
The first model anyone writes is the pinhole with the picture centred on the frame: a point at in front of the camera lands at
and the same for , with the middle of the frame and the focal length in pixels. It fails in three ways, all measured on the photographs below:
- The centre is not the middle. On OpenCV’s camera the optical axis meets the sensor 22 px right of the frame’s centre.
- Glass bends. With the centre right, the model is within 0.29 px of the corners near the middle of the frame and off by 5.75 px in the outer third, 13.3 px at the worst corner, because the lens bends rays more toward the edges.
- Wide angles have nowhere to go. A ray arriving off the axis lands at , which grows 4 times faster at 60° than at the centre and 33 times faster at 80°, and is infinite at 90°. On one fisheye lens the pinhole model with its best distortion terms predicts a ray at 80° at −35,572 px, a sign flip; the lens puts it at 458.8 px.
The better description names each pixel by the angle of the ray it receives, and describes a lens by one curve: how far from the centre, , a ray at that angle lands. A pinhole is ; real glass is that curve bent by a few measured coefficients; a fisheye is a different curve, such as , that stays finite at 90°.
With the centre measured and the bend modelled, the chessboard corners all land within 0.40 px, and on the fisheye the right curve fits to 0.64 px where the pinhole fitted 7.33. Lessons 1, 3 and 4 build that model one piece at a time [1] [2].
The photographs everything is measured on
Three public sets, one per problem, and every number on this page comes out of them rather than out of a textbook.
| Source | Used for | What it gives |
|---|---|---|
OpenCV’s own chessboard photographs, samples/data/left*.jpg | lessons 1 and 3 | 13 views of a board with 9×6 inner corners, 640×480, Apache-2.0 |
| One published scene from the DPDD dataset [7] | lesson 2 | the same bench at f/4 and f/22, 93 mm, focused at about 1.5 m |
| 15 fisheye views of a board with 6×8 inner corners, from the py-OCamCalib test set | lesson 4 | a lens wide enough to break the model taught in lessons 1 to 3 |
The chessboard set is the spine. It is thirteen ordinary photographs of a printed board held at different angles, and calibrating on it [5] yields the camera every lesson refers back to:
| Parameter | Value |
|---|---|
| , | 536.07 px, 536.02 px |
| , | 342.37 px, 235.54 px |
| , , | −0.2651, −0.0467, 0.2523 |
| RMS reprojection error | 0.4087 px over 13 views |
Two things in that table are worth pausing on before any lesson starts. The principal point sits 22 px right of centre and 4 px above it, so the optical axis does not pass through pixel (320, 240) even on a camera nobody dropped. And is negative, which is the signature of barrel distortion: the lens pulls the corners of the scene inward.
Topics
- Pinhole and perspective projection. Steps 2 and 4: why does a small hole produce a sharp picture at all, and what does the resulting projection do to parallel lines and to size with distance? The similar-triangles model, , and how far it lands from where the corner is [1].
- Lenses, focal length and depth of field. The focus branch: a hole small enough to be sharp is too dark to use. A lens fixes the light and introduces a plane of focus, so what is in focus and what is not [1]?
- Distortion, vignetting and aberration. Step 3: real glass bends rays more at the edges than the thin-lens model allows. How far does that move a pixel [3], and what does straightening it back cost you [2]?
- Wide-angle and fisheye models. Step 3, past about 120° of field: the pinhole puts a ray at , which runs to infinity at 90°. What replaces it [4]?
The order follows the light: the ray and its pixel first, the focus question that leaves from the ray, then the bend, then the curve that replaces the bend when the field is too wide.
What the unit measures
| Result | Measurement |
|---|---|
| A real lens moves a pixel a long way | The measured coefficients displace the worst image corner by 51.22 px on a 640×480 frame |
| Undistorting keeps the whole frame on this lens | Keeping the same , 0.00% of the output has no source pixel, and the view stays at 61.67° while the lens actually captured 67.32° |
| Stopping down deepens focus by the aperture ratio | Depth of field goes from 0.050 m at f/4 to 0.277 m at f/22, a factor of 5.54 against an aperture ratio of 5.50 |
| The wrong camera model costs an order of magnitude | On one fisheye lens, pinhole plus Brown–Conrady fits to 7.326 px RMS and Kannala–Brandt to 0.644 px, a factor of 11.4 |
Lesson 4 works the last row out in detail. Out to 45° the two models stay within 17% of each other and both grow smoothly. At 80° the pinhole prediction is −35,572 px, a sign flip rather than a large error, while the fisheye model keeps climbing to 458.8 px and then 502.1 px at 89°.
Run it: every code block on this page has a cell in the unit’s notebook: open it in Colab.
Limitations & caveats
- Two cameras, not a survey. The intrinsics, the distortion and the field-of-view results describe one lens, and the fisheye comparison describes one other. A different lens has different coefficients, and nothing here says how common these values are.
- The board’s physical square size is not published, so the calibration runs in board units. That leaves , , the principal point and every distortion coefficient unchanged, and it means no translation in this unit carries metres.
- Depth of field is computed, not observed. The f/4 interval is reproduced from the thin-lens formula and matches the published figure, which is a consistency check rather than a measurement of blur in the pixels.
- One row of the source figure does not reconcile. DPDD’s caption gives a f/22 depth of field of 0.70–5.80 m, which its own 93 mm focal length cannot produce; reproducing that interval would need a 29.1 mm lens at 1.249 m. Whether the row describes a different scene, a dataset-wide range or an error is not something the figure settles, so lesson 2 states the discrepancy rather than choosing for it.
- Reprojection error is not accuracy. It measures how well a model fits the points it was fitted to. A model with more free parameters will always score better on its own data, which is part of why the fisheye comparison uses two models with a comparable number of them.
What this means for your pipeline
- Calibrate before you measure. The pinhole with the frame’s middle as its centre is off by 5.75 px in the outer third of a 640×480 frame; with the measured centre and five distortion coefficients, 13 photos of a printed board bring every corner within 0.40 px.
- Straighten before you fit lines. A distortion of up to 51 px in the corners bends straight lines; on a court camera, straightening cut a measured error from 5.95 cm to 1.96 cm.
- Undistorting does not have to crop. Keeping the same focal length leaves 0.00% of the output empty on this lens, at the price of showing 61.67° where the lens saw 67.32°.
- Past about 120° of field, switch models. On one fisheye,
cv2.fisheyefits to 0.64 px where the pinhole with distortion fits to 7.33 px. - Stop down for depth. From f/4 to f/22 the depth in focus grew 5.54 times, close to the aperture ratio of 5.50, at the cost of light.
- What this does not tell you: how common these lenses are. Two cameras were measured, and a different lens has different coefficients.
Your turn: other cameras
For each camera below, say which step of the pipeline changes and how.
- A telecentric lens, used in industrial inspection, which sends every ray to the sensor parallel to the axis.
- A 360° camera built from two fisheyes back to back.
- A phone’s 120° ultra-wide, whose app shows straight lines straight.
Answers
- Step 2 changes: there is no division by depth. A telecentric lens maps to the sensor at the same size whatever the distance, , so a part measures the same in pixels near or far, which is why inspection uses it, and size no longer tells you distance.
- Step 3 has to reach past 90°. Each lens must see a little more than half the sphere so the two images overlap, and has no value past 90°. A fisheye curve such as keeps going, which is what lesson 4’s model allows.
- Step 3 runs backwards with a strong curve. At 60° off the axis, stretches the image 4 times faster than at the centre, so the app undistorts with the lens’s own coefficients and accepts stretched corners, or crops them.
Where this lands
The measured closer is what is a homography. Its court
camera is not a pinhole: the near baseline bows by 7.7 px across the frame. A
one-parameter radial model fitted to the near court lines straightens it to 0.16 px and
cuts the far-sideline error of the court homography from 5.95 cm to 1.96 cm, which is
lesson 3’s correction paying for itself on a real measurement. What undistortion costs
per frame on real hardware (cv2.remap with a precomputed map against cv2.undistort
per frame, at 1080p) is still unmeasured.
What does depend on this unit is everything downstream that assumes a rectilinear image: SIFT matching points across views, RANSAC fitting a model to those matches, and structure from motion, which needs a calibrated camera before it can triangulate anything.
How these numbers were made
| Parameter | Value |
|---|---|
| CPU | 12th Gen Intel Core i7-12700H, 20 threads |
| GPU | none used; every fit here runs on the CPU |
| RAM / OS | 31 GB · Ubuntu 22.04.5 LTS, kernel 6.8.0-136 |
| Key versions | Python 3.12.9, OpenCV 5.0.0 [6], NumPy 2.5.2 |
| Data | OpenCV samples/data/left*.jpg (13 views, Apache-2.0) · py-OCamCalib test_images/fish_1 (15 views, GPL-2.0, downloaded not redistributed) · capture settings read off DPDD’s figures/data_example.png [7] |
| Commands | uv run formation-download, then uv run formation-calibrate, formation-distort, formation-dof, formation-fisheye; the photographs come from uv run data-experiments |
| In the wild | Four Wikimedia Commons files, all CC0: a temple cloister, a market stall, a brick wall and a circular fisheye frame. Registered in CondadosAI/cv-assets with the licence read from the Commons API and a sha256 pinning the bytes measured; downloaded, never redistributed |
| Runs | every result is a deterministic fit, run once; no averaging, no seed |
| Excluded | no timing is reported in this unit; every number is a geometric quantity or a reprojection error |
Every number above is a key in output/formation_numbers.json or the printed output of a
cell on a lesson page, which the unit notebook reproduces; the “in the wild”
figures are keys in output/image_data_numbers.json under in_the_wild_other_units.
Two lesson figures are derived on the page from those keys rather than stored: lesson
3’s linear-light vignetting estimate (the stored code values decoded through the sRGB
curve) and lesson 4’s equisolid image-circle prediction (the stored focal length and
pixel pitch). The lessons themselves carry no reproducibility table; this one covers
all four, which is how unit 3.1 has always worked and how the whole track now works.
Each lesson also repeats its measurement on a photograph, because these four were measured on calibration targets and a calibration target is not a picture anybody takes. Lesson 1 fits a vanishing point to 53 lines of a temple cloister and lands within 1.6% of the frame diagonal; lesson 2 reads a Nikon’s own EXIF and predicts 0.59 m of depth at 300 mm and f/4; lesson 3 measures 0.22 stops of corner falloff on a brick wall in the JPEG’s code values, about half a stop once decoded to linear light; lesson 4 measures a fisheye’s image circle at 1752 px, within 1.9% of the equisolid prediction (1720 px) and 8.3% short of the equidistant one (1910 px).
Further reading
- Go deeper: Forsyth & Ponce, Computer Vision: A Modern Approach (2nd ed.), ch. 1 “Geometric Camera Models” [1]. Sections 1.1.1 and 1.1.3 cover lessons 1 and 2 in twelve pages, and its split between §1.1 and §1.2 is the same boundary this unit draws.
- For the algebra: Hartley & Zisserman, ch. 6 “Camera Models” [2], once you want the projective form rather than the two scalar equations.
- Related on CondadosAI: camera geometry is the sequel that turns this geometry into a matrix · the image as data is what the sensor’s output turns into.
References
[1] Forsyth, D. A., & Ponce, J. (2012). Computer Vision: A Modern Approach (2nd ed.), ch. 1 “Geometric Camera Models”, §1.1.1 “Pinhole Perspective” (p. 4) and §1.1.3 “Cameras with Lenses” (p. 8). Pearson.
[2] Hartley, R., & Zisserman, A. (2004). Multiple View Geometry in Computer Vision (2nd ed.), ch. 6 “Camera Models” (p. 153) and §7.4 “Radial distortion” (p. 189). Cambridge University Press.
[3] Brown, D. C. (1971). Close-range camera calibration. Photogrammetric Engineering, 37(8), 855–866.
[4] Kannala, J., & Brandt, S. S. (2006). A Generic Camera Model and Calibration Method for Conventional, Wide-Angle, and Fish-Eye Lenses. IEEE Transactions on Pattern Analysis and Machine Intelligence, 28(8), 1335–1340. doi:10.1109/TPAMI.2006.153
[5] Zhang, Z. (2000). A flexible new technique for camera calibration. IEEE Transactions on Pattern Analysis and Machine Intelligence, 22(11), 1330–1334. doi:10.1109/34.888718
[6] OpenCV Documentation (5.0). Camera calibration and 3D reconstruction and Fisheye camera model. docs.opencv.org/5.0
[7] Abuolaim, A., & Brown, M. S. (2020). Defocus Deblurring Using Dual-Pixel Data. European Conference on Computer Vision (ECCV) 2020. arXiv:2005.00305