
Computer Vision, understood.
Then shipped.
Benchmarks that name the hardware they ran on and publish the code behind every number, and a Fundamentals track that teaches the ideas underneath them, with interactive demos and runnable Python & C++.
New posts by email: subscribe. Or browse every post, newest first.
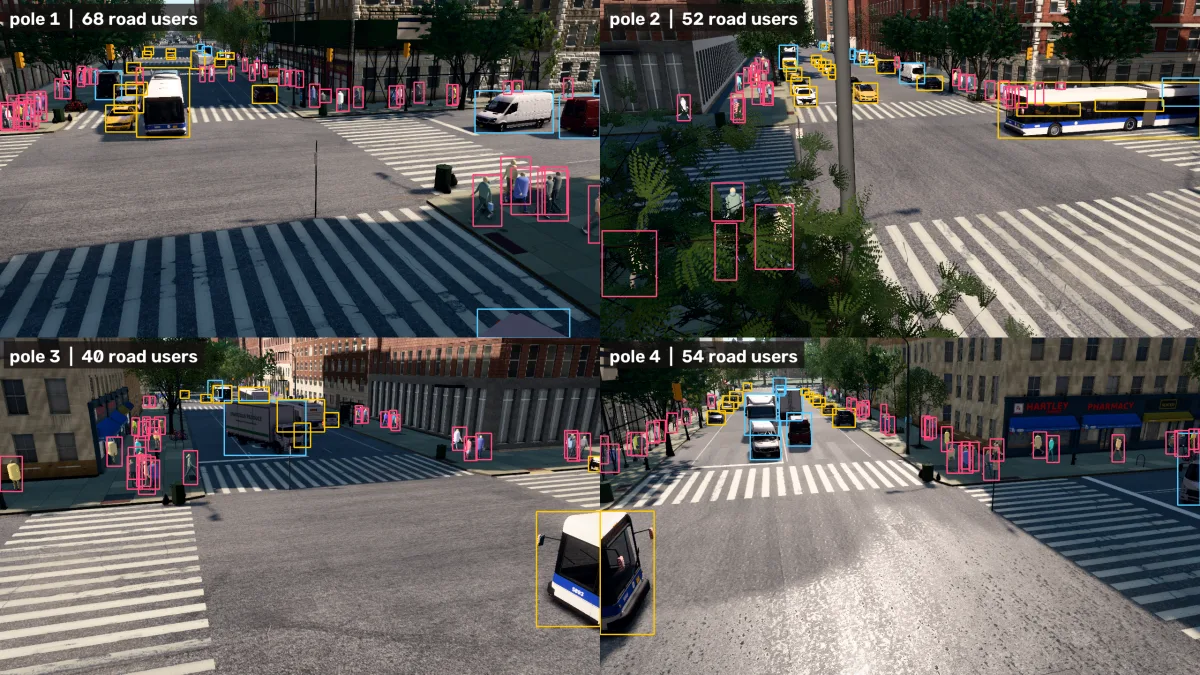
A Traffic Camera in a Simulated New York: Exact Labels at 0.75 s a Frame
A pole camera at a real Harlem junction, rendered by the Valdrada simulator on one desktop GPU: every car and pedestrian comes with its box, its mask, its depth and how much of it is hidden, at 0.75 s per labelled frame when four cameras share a capture. What it took to run headless on Linux, what a simulated label does and does not tell you, how far a COCO detector gets on it, and a recording format that lets the same code read a real camera later.
Projects and benchmarks
Measured on named hardware, with the code to reproduce every number.
 Edge Deployment
EmbeddingGemma 2 Video Search on a Laptop iGPU
Google's open EmbeddingGemma 2 finds the right clip for a sentence 22 times out of 23, fully offline, at 2.3 s per clip on the Intel Iris Xe inside a laptop with OpenVINO INT8. Then the same vectors are asked which way time runs: a clip and its reverse land at cosine 0.997, and neither EmbeddingGemma 2 nor VideoPrism, a model built for video, can tell them apart.
 Edge Deployment
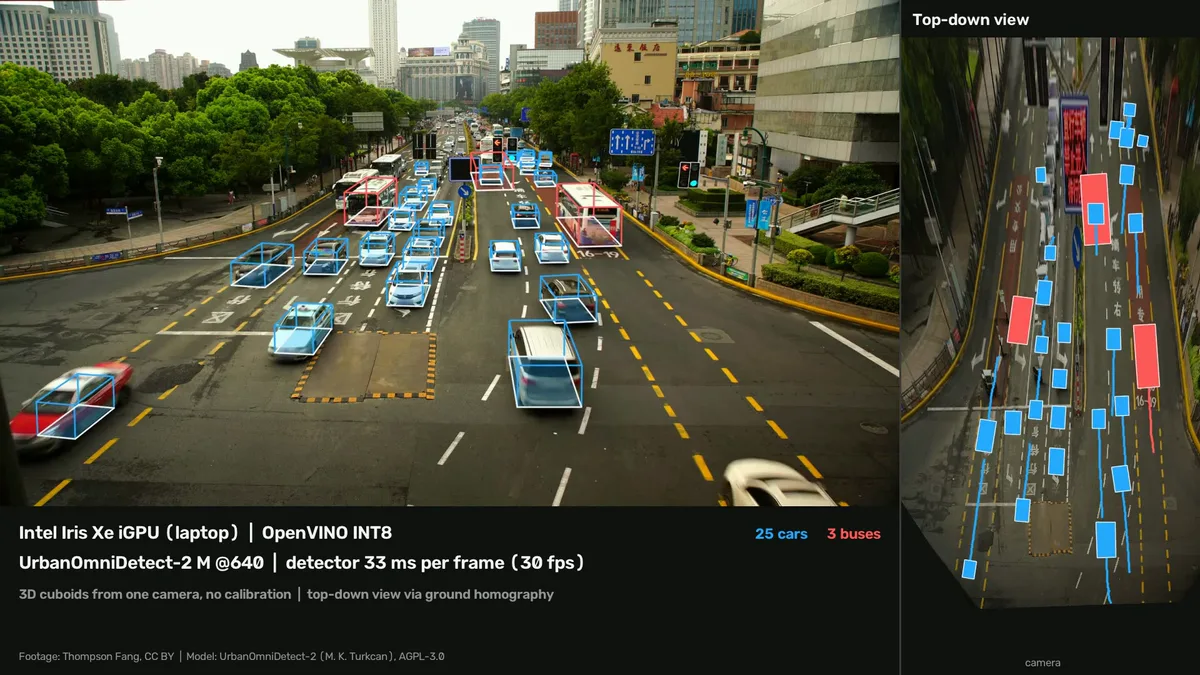
3D Vehicle Detection on a Laptop iGPU
UrbanOmniDetect-2 draws a 3D box around every vehicle from one uncalibrated camera and places it on a top-down map of the road. On the Intel Iris Xe inside a 12th-gen laptop, quantized to INT8 with OpenVINO and with its final layer kept in float, the medium model runs at 33 ms per frame (30 fps), and its box corners stay within 0.4 px of the original model on two traffic cameras.
 Evaluation
How many good parts does it take to beat a System One AI model? Between one and sixteen, on VisA
System One models, the idea TypeSafe launched with Jev in September 2026, answer a question with a decision in a single pass. Jev-Omni, an open one, and the untouched Gemma 4 12B it was built from inspect all 2,162 VisA test images without seeing a good part. PatchCore, the standard industrial anomaly detector, is given k good parts per product: at 256 pixels it passes Jev-Omni at k = 8 and Gemma 4 at k = 16, at 512 pixels at k = 1 and k = 4. Also: the base model beats its System One fine-tune, and a day-0 demo on a lime line.
Learn computer vision, in order
The Fundamentals track, from how a camera forms an image onwards. Each unit opens with an overview and builds on the ones before it.
Image formation
How a scene is flattened onto a sensor, and what the glass does on the way.
Image sensing
What the number in a pixel counts, and how far it can be trusted.
The image as data
What the array holds, where its samples sit, how finely they are written, and what the file did to them.
Spatial filtering
The one operation behind blur, sharpening, edges and every CNN.
Edge detection
Finding where one thing stops and another begins.
Boundary detection
Finding lines and circles by voting: the Hough transform, and fitting one line to what it finds.
Evaluating a model? The Metrics Handbook builds every score in the field from one confusion matrix.
Browse by topic
Everything on the site, from how images work to models running on edge hardware.
Get new posts by email
New explainers, interactive demos, and benchmarked projects as they publish, plus short notes on computer vision and the AI world.