
quantization
6 posts · browse all tags
 Edge Deployment
EmbeddingGemma 2 Video Search on a Laptop iGPU
Google's open EmbeddingGemma 2 finds the right clip for a sentence 22 times out of 23, fully offline, at 2.3 s per clip on the Intel Iris Xe inside a laptop with OpenVINO INT8. Then the same vectors are asked which way time runs: a clip and its reverse land at cosine 0.997, and neither EmbeddingGemma 2 nor VideoPrism, a model built for video, can tell them apart.
 Edge Deployment
3D Vehicle Detection on a Laptop iGPU
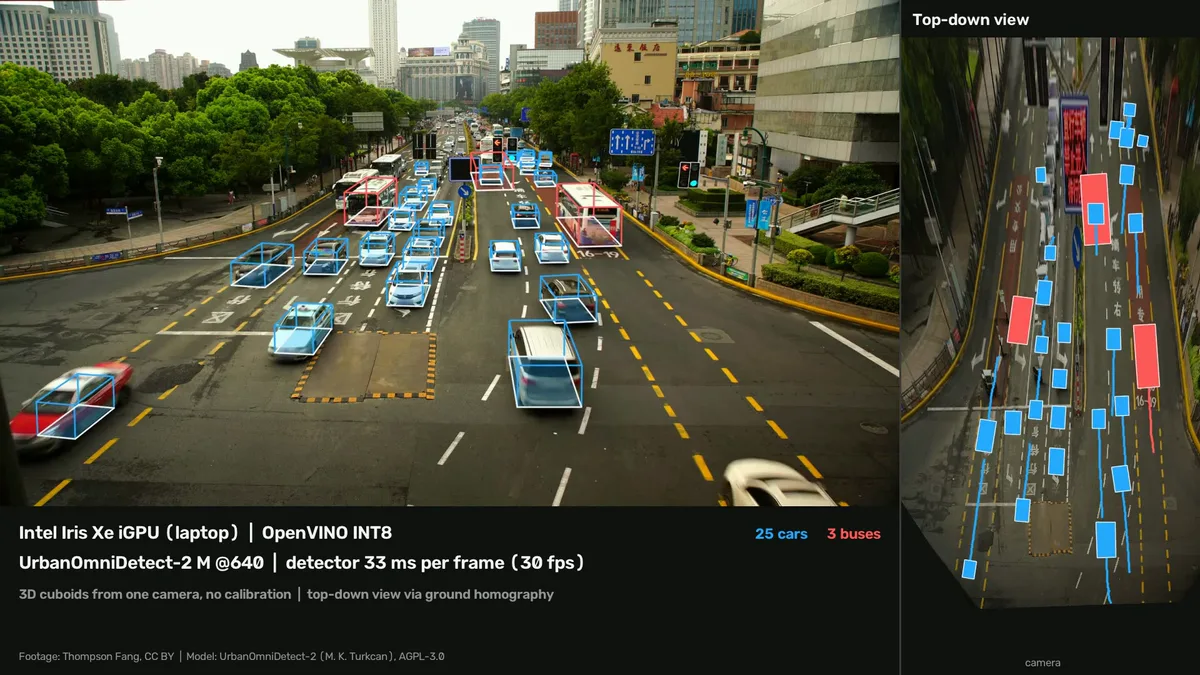
UrbanOmniDetect-2 draws a 3D box around every vehicle from one uncalibrated camera and places it on a top-down map of the road. On the Intel Iris Xe inside a 12th-gen laptop, quantized to INT8 with OpenVINO and with its final layer kept in float, the medium model runs at 33 ms per frame (30 fps), and its box corners stay within 0.4 px of the original model on two traffic cameras.
 Edge Deployment
Marigold V2 at four bits: what quantizing a 20-billion-parameter depth model costs
Marigold V2 ships as a 17 GB inference job, but the released checkpoint is a rank-128 LoRA over a frozen 20.4 B backbone, so the backbone is swappable. Four configurations on one rented A40: going 4-bit costs 10% of the time and saves 65% of the memory, picking GGUF over bitsandbytes costs another 1.87x and saves nothing, and streaming the weights from host RAM costs 3.33x.
 Models & Detection
YOLO-NAS Strikes Back: Still the Fastest Detector on Hardware You Already Own
Quantized to INT8, YOLO-NAS-S runs at 201 FPS on a laptop CPU and gives up 0.4 AP on COCO for it, and it drops straight into Frigate. The model aged well; its tooling did not. Here is a clean reimplementation, measured across CPU, Intel iGPU and NVIDIA dGPU, and checked bit-for-bit against the original.
 Edge Deployment
RF-DETR vs YOLO-NAS: A Practical Benchmark for Edge Deployment: CPU, GPU, and Intel iGPU Compared
RF-DETR Nano vs YOLO-NAS-S on COCO across CPU, CUDA GPU, and Intel Iris Xe iGPU, across two resolutions, OpenVINO FP32/FP16/INT8, and a custom fine-tune, all under one consistent evaluation. RF-DETR wins accuracy; YOLO-NAS wins latency, efficiency, and INT8.
 Models & Detection
CNN vs Transformer, quantized: YOLO26-seg and RF-DETR-Seg race for instance masks on an Intel iGPU
Two opposite small segmentation models, a 2026-era CNN and a DETR transformer, both quantized to INT8 with NNCF and run on a laptop Intel iGPU. YOLO26-seg's forward pass is ~7.4× faster; RF-DETR-Seg keeps its masks more faithful under INT8 on the CPU, and its fully-quantized mask head breaks on the iGPU. The whole shootout, numbers first.