
Before this unit: 2D convolution
Edge Detection: Finding Where One Thing Stops and Another Begins
How to find, in any photo, the places where one thing stops and another begins, and turn them into a clean black-and-white edge map. One pipeline, from grey to smoothed to the change at every pixel to thin linked edges, with corners as a branch, measured on one photo and shown step by step on another.
This unit is about finding the places in an image where one thing stops and another begins: a line painted on a court, the outline of a player, the border of a page. The same steps work on any grid of numbers, so they find edges in a depth map, a thermal image or a medical scan as well as in a photo. The animation shows the finished result: a match on top, and underneath the edges Canny’s method finds in it, frame by frame.
Every lesson is one step of the same pipeline, or a branch off it:
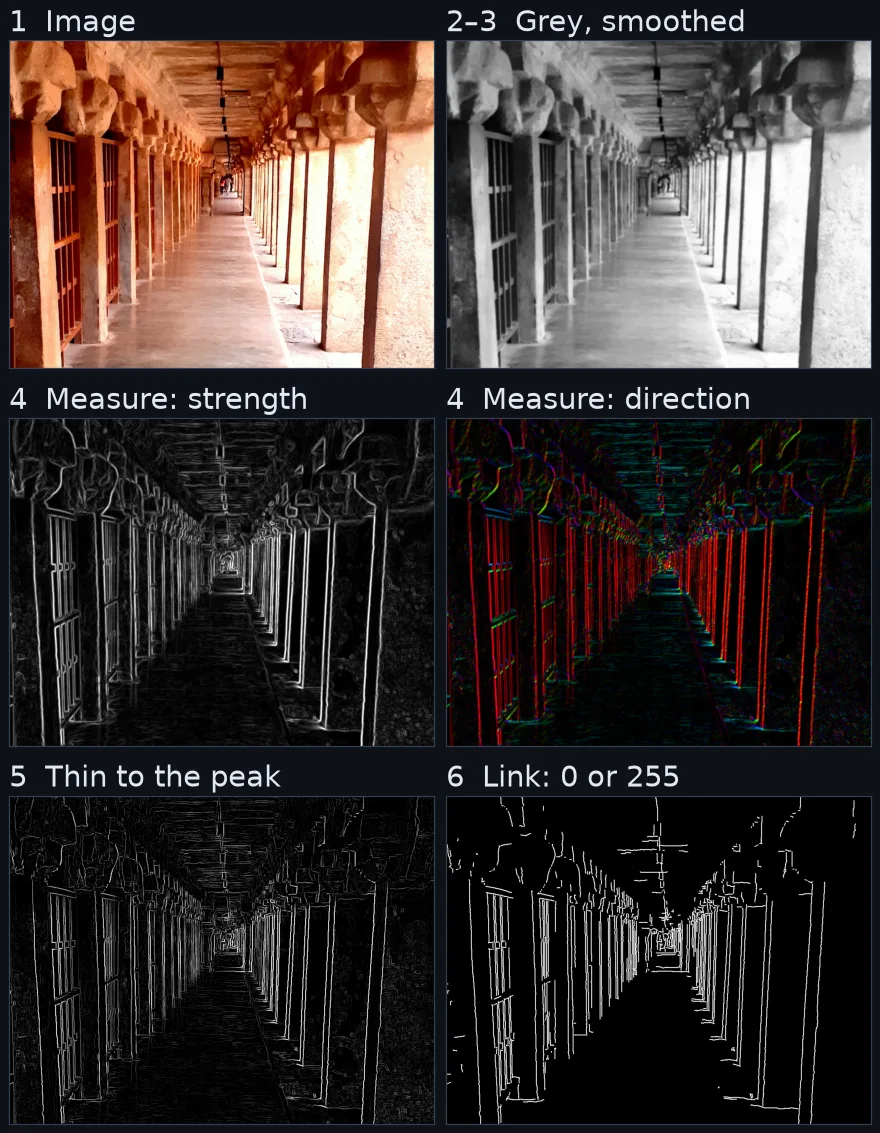
- Image. A photo, in colour or not.
- Grey. One brightness number per pixel. An edge is where that number changes fast.
- Smooth. Blur the image slightly first, so that noise from the sensor does not look like thousands of tiny edges. A Gaussian blur of σ 1.4 px is the usual choice.
- Measure the change. At every pixel, how much the brightness changes and in which direction: the gradient, from two small kernels, one across and one down (lesson 2). The second derivative is the alternative way to measure it (lesson 4).
- Thin. A real edge is a ramp a few pixels wide, so its strength is a ridge a few pixels wide. Keep only the pixel at the top of the ridge, compared across the edge using the direction from step 4 (lesson 3).
- Link. Keep strong edge pixels, and weak ones only where they connect to strong ones, so a contour survives where it fades and isolated specks do not (lesson 3).
- Use the edge map. Every pixel is now 0 or 255: the input for finding lines and circles (unit 3.2), measuring a part, or squaring up a page.
The corner branch leaves at step 4: instead of asking whether the brightness changes in one direction, it asks whether it changes in two at once, and returns points instead of curves (lesson 5).
What the outputs are used for
You have met these outputs in everyday tools, and each of them acts on what the pipeline returns:
- Measurement on a production line. Two edges found along a line across a part give its width in millimetres, and the part passes or fails on that number.
- Lane-keeping and line-finding. The edge map is what the Hough transform of unit 3.2 votes on to find lane lines and their angle.
- Document scanners. The page’s border, found as edges, gives four corners, and the corners give the homography that flattens it.
- Contrast autofocus. The camera moves the lens until edge strength peaks: a sharper image has steeper edges.
- Barcode readers turn the places where one scanned line switches from dark to light into bar widths.
- Lens calibration and tracking. The corners of a printed chessboard, from the corner branch, are what calibration fits a camera model to; corners tracked from frame to frame are what stabilisation follows.
An edge detector finds the outlines in a picture, and the version that works smooths first, measures the change and its direction, then thins and links what it finds. On the temple photo the lessons measure on, averaging across rows keeps 0.7968 of the clean edge set at heavy noise against 0.6262 without it, and linking returns 204 contours averaging 18.68 px where a single threshold keeping the same pixels returns 393 averaging 9.69 px.
Before this
You need 2D convolution. Every operator here is a small kernel slid over the image, and the separability trick from that post is what makes the 3×3 gradient operators cheap. If the image is still a black box, start at how a camera forms an image and the image as data.
How to write down an edge
To find edges, a program needs a rule it can evaluate at each pixel and a description of what it found.
The first rule anyone writes is a threshold: a pixel is on an edge when the brightness changes by more than some amount there. Measured on the cloister above, after the same σ 1.4 blur, that rule gives edges several pixels wide, and raising the threshold narrows them only by throwing structure away:
| threshold (0–255) | edge width | share of the low threshold’s edges kept |
|---|---|---|
| 10 | 5.38 px | 100% |
| 40 | 4.42 px | 48.6% |
| 160 | 2.78 px | 15.3% |
No threshold gives a one-pixel edge, and the cost of a high one is coverage. Edges do not break into more pieces as it rises: the number of separate fragments falls from 14,420 to 689, because weak structure disappears outright. A rule that only compares a pixel with its neighbour along the row also has a blind spot: it sees the pillars’ sides and misses the horizontal edges, the lintels and the floor joints that cross the corridor.
The better description is the gradient, a small arrow at every pixel. Its length is how fast the brightness changes, and its direction is the way it changes fastest, which points straight across the edge:
where and are the change measured across and down.
The direction is what fixes the width. Step 5 compares each pixel with its two neighbours along , across the edge, and keeps it only if it is the strongest of the three, so a ridge five pixels wide becomes one. The threshold is then free to do the other job, deciding what is an edge at all, and linking does it better than a single cut: on the cloister, at the same 21,181 edge pixels, linking returns 627 contours averaging 33.78 px where a single threshold returns 1,205 averaging 17.58 px. The same direction is what the Hough transform of unit 3.2 reuses to vote for fewer lines.
A corner needs one more idea. Along an edge the brightness changes in one direction only, so a point on it cannot be told from its neighbours along the edge. At a corner it changes in two. Lesson 5 describes the neighbourhood of a pixel by a 2×2 matrix of gradient products, whose two eigenvalues say how much the brightness changes in its strongest and weakest direction: both small on flat background, one large on an edge, both large at a corner.
The photograph everything is measured on
Every lesson works on one image: view 0 of the Middlebury templeRing set
[6], a plaster temple against a black backdrop, 640×480. It is the temple the
SIFT unit walks around for its viewpoint test,
rotated upright, contrast-lifted and resized to 360×480 once. Using one image the
whole way through means a number from lesson 2 can be compared against a number
from lesson 5 without re-anchoring. The pipeline above is drawn on the cloister instead, a
photograph the lessons also use for their “in the wild” checks.
Three places in that frame carry the unit:
- the black background, where nothing changes in any direction;
- a column’s silhouette against it, where brightness changes across the edge and not along it;
- the corner where the base meets a column, where it changes in both directions at once.
Tracing the silhouette with a pencil is edge detection. The background has nothing to trace. The corner is where two edges meet, which turns out to be a different problem with a different answer, and that is the last lesson.
Topics
- What is an edge? The criterion behind every step: if you had to define an edge with arithmetic instead of a pencil, what would you write? Step, ramp and roof profiles, and the fact that an edge is a peak in the first derivative and a zero-crossing in the second [1].
- Gradients: central differences, Prewitt, Sobel. Step 4: how do you measure the change in two directions, and why do three operators that answer the same question behave so differently on a noisy photo?
- Canny. Steps 5 and 6: thresholding a gradient gives edges that are too thick, then too broken, and never both right. Canny’s answer was two separate ideas: thin the ridge, then decide membership by connection [2].
- The Laplacian, LoG and zero-crossings. The alternative at step 4: the second derivative places an edge with no ridge to thin. What does Marr and Hildreth’s method cost you [3], and why does it need smoothing before it is usable at all?
- Corners: the structure tensor. The branch off step 4: a contour tells you where a boundary runs but not where you are along it. Two eigenvalues fix that [4], and they are where the SIFT unit begins.
The order follows the pipeline. Lesson 1 is the rule every step serves, lessons 2 and 3 are the steps in the order an image goes through them, lesson 4 is the other way to do step 4 and what it costs, and lesson 5 leaves the pipeline at step 4 to find points.
What the unit measures
Every lesson carries its own numbers. These results shape the pipeline above; the first four
are computed on the temple frame and the last on the hub’s cloister, all saved in
output/edge_numbers.json:
| Result | Measurement |
|---|---|
| Averaging across rows is what buys noise robustness | At noise , a plain central difference recovers 0.6262 of its clean edge set; Prewitt recovers 0.7968 and Sobel 0.7814 |
| Sobel is not the better operator for noise | Prewitt leads Sobel at every noise level tested; the gap is 1.5× the larger run-to-run standard deviation at and 3.4× at |
| Linking beats thresholding at equal cost | At 3,810 edge pixels, hysteresis returns 204 contours averaging 18.68 px; a single threshold keeping the same pixels returns 393 averaging 9.69 px |
| Smoothing is what makes zero-crossings usable | Noise multiplies the crossing pixels by 2.76× at and by 1.02× at |
| A threshold alone cannot make an edge thin (cloister) | At threshold 10 edges are 5.38 px wide; at 160 they are 2.78 px with 15.3% of the structure kept. At 21,181 edge pixels, linking gives 627 contours of 33.78 px against 1,205 of 17.58 px |
The Prewitt result has a mechanism behind it, and lesson 2 works it out: for the same three-row support, Prewitt’s normalised weights have against Sobel’s , so Prewitt passes about 11% less noise power. What Sobel’s buys is rotational symmetry.
Limitations & caveats
- One scenario image. The operator comparisons are measured on a single 360×480 photograph of a plaster temple; the cloister, newspaper and market-stall numbers are one check each, not a benchmark. The Prewitt-over-Sobel ordering held at every noise level tested on the temple, which makes variance an unlikely explanation and is not enough to make it a claim about photographs in general.
- There is no ground truth here. “Agreement” means agreement with the same operator’s own result on the clean image. It measures stability under noise, not correctness. No human labelled these edges, and an operator that is confidently wrong in the same place twice scores perfectly.
- The noise is synthetic. Gaussian noise added in software is not sensor noise. Real read noise is signal-dependent, and demosaicing correlates it between neighbouring pixels, which is the structure these operators average over.
- The 5% edge budget is a choice. It makes operators with different response scales comparable, and it also fixes how much of the image is called an edge. A different budget moves the absolute numbers.
- The hub’s pipeline runs on a different photograph from the lessons. The panels and the threshold and linking numbers in “How to write down an edge” are measured on the cloister, which the page can show in full; the lessons and the table above measure on the temple. The same functions run on both, and the two agree in direction and roughly in size.
- Nothing is timed. All four operators cost a 3×3 convolution and the differences would be noise on any machine that matters.
What this means for your pipeline
- Smooth before you differentiate. An operator that averages across rows keeps 0.7968 of the clean edges at heavy noise against 0.6262 for a plain difference, and smoothing takes the Laplacian’s noise-made crossings from 2.76× to 1.02×.
- Pick Prewitt or Sobel for what you need. Prewitt passes about 11% less noise power; Sobel gives a closer response at every angle.
- Use
cv2.Cannyrather than a threshold on the gradient. At the same pixel budget it returns contours about twice as long (204 against 393 pieces). It does no smoothing of its own, so blur first, and retune its thresholds after blurring: blurring lowers the gradient, and on lesson 3’s test square a weak side survives on 79 of 80 rows before the blur and 1 after. - For corners, prefer Shi-Tomasi. Harris’s constant decides the answer on an edge patch (it flips sign at ); Shi-Tomasi reads the smaller eigenvalue and has no constant.
- What this does not tell you: which edges are the right ones. No person labelled these edges, so every agreement number here is stability under noise, not correctness.
Your turn: other kinds of change
The pipeline finds a fast change in one number per pixel. For each case below, say which step fails or what you would change.
- A thin bright line, such as a white court line two pixels wide, on a dark floor.
- A boundary between red and green of the same brightness.
- The same edge in two frames of a video, when you want to know whether it moved.
Answers
- The line is a roof, not a step: brightness goes up and straight back down. The gradient has two peaks, one on each side of the line, so thinning keeps two edges a couple of pixels apart, and the second derivative crosses zero twice. To find the line itself, look for the ridge (a peak in brightness) instead of the edge; lesson 1 works the roof profile.
- Step 2 loses it. Grey keeps one brightness number per pixel, and two colours of equal brightness give the same number, so there is no change to measure. Run steps 3 to 5 on each colour channel and keep the strongest gradient per pixel, or measure the change in a colour space where the two differ.
- Time is one more direction of change. Differencing the two frames is the gradient along time; the structure tensor of lesson 5 extended with that third direction is the starting point of optical flow, which asks how far each edge moved.
Where this lands
Lesson 5’s corners are where SIFT starts: its first lesson asks whether such points are found again when the camera turns or moves closer. The contours from lesson 3 are the input the next unit, boundary detection, fits lines and shapes to. Gonzalez and Woods put the Hough transform in the same section as Canny for that reason [1].
How these numbers were made
| Parameter | Value |
|---|---|
| CPU | 12th Gen Intel Core i7-12700H, 20 threads |
| GPU | none used; every operator here runs on the CPU |
| RAM / OS | 31 GB · Ubuntu 22.04.5 LTS, kernel 6.8.0-136 |
| Key versions | Python 3.12.9, OpenCV 5.0.0 [7], NumPy 2.5.2 |
| Data | Middlebury templeRing view 0 [6], 640×480, preprocessed to 360×480 |
| Data (in the wild) | Three Wikimedia Commons photographs, all CC0, registered in CondadosAI/cv-assets with a sha256 each and fetched at run time (the hub serves renders of a crop of the cloister, which CC0 allows): “The Cloister Mandapam, in One point perspective” by Sindugab (cloister, lessons 1, 2, 4); “Departementaal Dagblad van de Zuiderzee… 30 maart 1814” by the Rijksmuseum (newspaper-1814, lesson 3, a 700×700 crop); “Marrakech souk fruit vendor” by Mustang Joe (souk-fruit, lesson 5) |
| Data (hub pipeline) | the same cloister photograph (CC0, so the hub shows renders of it) at 960 px wide, its middle 960×720; panels and the hub_cloister numbers in output/edge_numbers.json |
| Commands | uv run edge-download then uv run edge-experiments for the canonical frame; uv run data-experiments for the photographs; uv run boundary-download then uv run edge-hub for the hub’s cloister panels and numbers |
| Runs | noise results are the mean of 5 realizations from seed 20260818; the standard deviation of each is in the JSON |
| Excluded | no timing is reported in this unit; every number is an accuracy or a count |
Every number in the measurement table above is a key in output/edge_numbers.json, the
cloister rows under hub_cloister.
The in-the-wild numbers below are under in_the_wild_other_units.unit_3_1 in
output/image_data_numbers.json.
The lessons carry no reproducibility table of their own, and each of them also repeats
its measurement on a photograph as well as on the unit’s frame. A temple cloister gives
edges a median width of 2.30 px, with 98.8% of the 400 measured wider than two
pixels, and puts 65.5% of its strong gradients into two orientation bands. An 1814
newspaper shows 96.3% of the Laplacian’s zero-crossings sitting where nothing is
changing. Hysteresis on the cloister returns 654 long contours out of 4,340, against
73,025 fragments from the low threshold alone. And Harris corners on a market stall come
back 85–88% of the time under rotation. The photographs are Wikimedia Commons files
under CC0, registered in CondadosAI/cv-assets with verified licences and a sha256 each,
and downloaded at run time; the hub’s pipeline figure is a render of a crop of the cloister.
Further reading
- Go deeper: Gonzalez & Woods, Digital Image Processing (4th ed.), §10.2 “Point, Line, and Edge Detection” [1]. It covers this unit end to end, including the Hough transform we defer to the next one.
- The wider map: Szeliski, ch. 7 “Feature Detection and Matching” [5], for where edges sit relative to everything built on them.
- Related on CondadosAI: 2D convolution is the prerequisite · SIFT is the sequel, and it is where these corners stop being points and start being descriptors.
References
[1] Gonzalez, R. C., & Woods, R. E. (2018). Digital Image Processing (4th ed.), ch. 10 “Image Segmentation I: Edge Detection, Thresholding, and Region Detection”, §10.2 “Point, Line, and Edge Detection”, pp. 763–804. Pearson.
[2] Canny, J. F. (1986). A Computational Approach to Edge Detection. IEEE Transactions on Pattern Analysis and Machine Intelligence, 8(6), 679–698. doi:10.1109/TPAMI.1986.4767851
[3] Marr, D., & Hildreth, E. (1980). Theory of edge detection. Proceedings of the Royal Society of London B, 207(1167), 187–217. doi:10.1098/rspb.1980.0020
[4] Harris, C. G., & Stephens, M. (1988). A Combined Corner and Edge Detector. Proceedings of the Alvey Vision Conference 1988, pp. 1–6. doi:10.5244/C.2.23
[5] Szeliski, R. (2022). Computer Vision: Algorithms and Applications (2nd ed.), ch. 7 “Feature Detection and Matching”. Springer. Free PDF
[6] Seitz, S. M., Curless, B., Diebel, J., Scharstein, D., & Szeliski, R. (2006). A Comparison and Evaluation of Multi-View Stereo Reconstruction Algorithms. CVPR 2006, pp. 519–528. doi:10.1109/CVPR.2006.19. The Middlebury multi-view datasets: vision.middlebury.edu/mview
[7] OpenCV Documentation (5.0). Image Processing: Canny Edge Detector. docs.opencv.org/5.0