
Proyectos y benchmarks
Modelos medidos en hardware identificado en el artículo, y sistemas construidos de principio a fin. Cada uno dice dónde se ejecutó, cómo se cronometró y dónde falla, y enlaza el repositorio que reproduce sus números.
¿Vas a comparar detectores o segmentadores por tu cuenta? La Guía de Métricas explica cada métrica que reportan estos artículos, y Aprender cubre los fundamentos que hay debajo.
 Edge
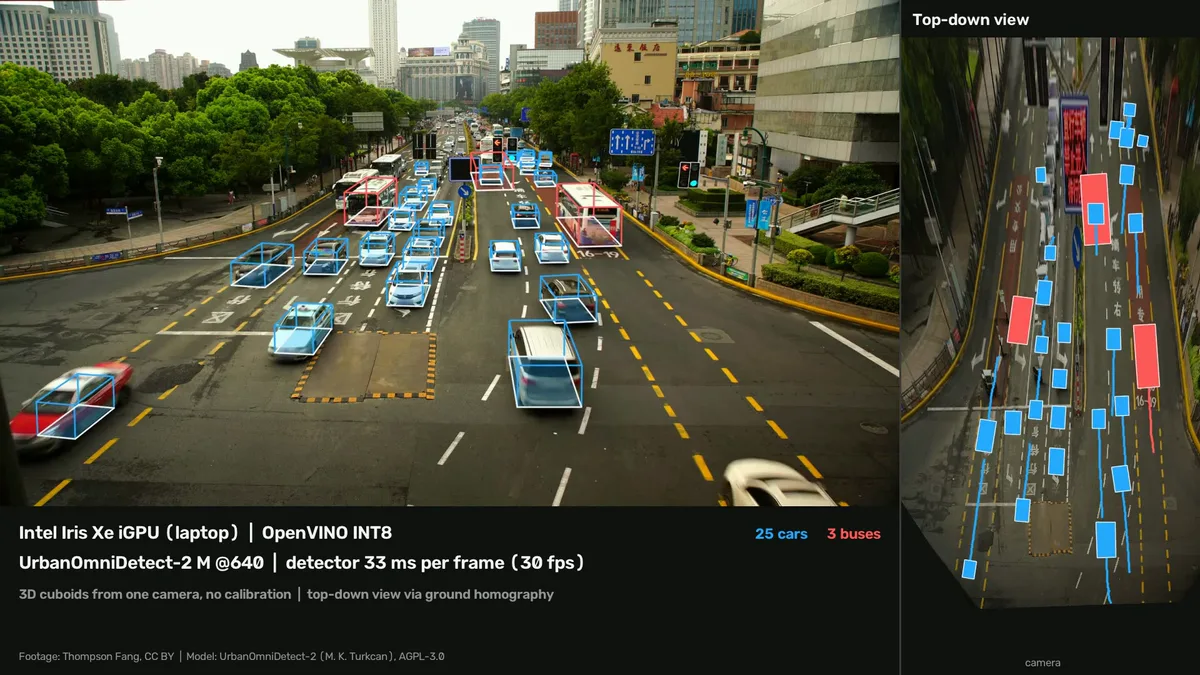
3D Vehicle Detection on a Laptop iGPU
UrbanOmniDetect-2 draws a 3D box around every vehicle from one uncalibrated camera and places it on a top-down map of the road. On the Intel Iris Xe inside a 12th-gen laptop, quantized to INT8 with OpenVINO and with its final layer kept in float, the medium model runs at 33 ms per frame (30 fps), and its box corners stay within 0.4 px of the original model on two traffic cameras.
 Evaluación
How many good parts does it take to beat a System One AI model? Between one and sixteen, on VisA
System One models, the idea TypeSafe launched with Jev in September 2026, answer a question with a decision in a single pass. Jev-Omni, an open one, and the untouched Gemma 4 12B it was built from inspect all 2,162 VisA test images without seeing a good part. PatchCore, the standard industrial anomaly detector, is given k good parts per product: at 256 pixels it passes Jev-Omni at k = 8 and Gemma 4 at k = 16, at 512 pixels at k = 1 and k = 4. Also: the base model beats its System One fine-tune, and a day-0 demo on a lime line.
 Edge
Marigold V2 at four bits: what quantizing a 20-billion-parameter depth model costs
Marigold V2 ships as a 17 GB inference job, but the released checkpoint is a rank-128 LoRA over a frozen 20.4 B backbone, so the backbone is swappable. Four configurations on one rented A40: going 4-bit costs 10% of the time and saves 65% of the memory, picking GGUF over bitsandbytes costs another 1.87x and saves nothing, and streaming the weights from host RAM costs 3.33x.
 Edge
Build a computer-vision plugin for OBS Studio, and measure what every frame costs
A step-by-step OBS Studio video filter in C++ on OpenVINO, split so the model swaps without touching the plumbing, and measured stage by stage: getting pixels off the GPU, where inference has to live so OBS never drops a frame, and what the trip from camera to virtual camera costs.
 Evaluación
How to build a rep counter that does not count your rest
A step-by-step build of exercise repetition counting on MediaPipe pose landmarks, in the browser. Each design decision is settled with a measurement: why the joint angle comes from world landmarks, why the 1 euro filter beats an exponential moving average by 44 percent at a 100 ms lag budget, and why one threshold turns six push-ups into twenty.
 Modelos y detección
Reproducing a published pupil-diameter model, and running it in the browser
An independent run of Shah et al.'s released PupilSense checkpoints over all 424,000 EyeDentify crops, then the whole thing converted to ONNX and put in a browser tab: what the quantisation costs, what the preprocessing port costs, where the compute goes, and what I would change to make it both cheaper and more trustworthy.
 Modelos y detección
YOLO-NAS Strikes Back: Still the Fastest Detector on Hardware You Already Own
Quantized to INT8, YOLO-NAS-S runs at 201 FPS on a laptop CPU and gives up 0.4 AP on COCO for it, and it drops straight into Frigate. The model aged well; its tooling did not. Here is a clean reimplementation, measured across CPU, Intel iGPU and NVIDIA dGPU, and checked bit-for-bit against the original.
 Edge
RF-DETR vs YOLO-NAS: A Practical Benchmark for Edge Deployment: CPU, GPU, and Intel iGPU Compared
RF-DETR Nano vs YOLO-NAS-S on COCO across CPU, CUDA GPU, and Intel Iris Xe iGPU, across two resolutions, OpenVINO FP32/FP16/INT8, and a custom fine-tune, all under one consistent evaluation. RF-DETR wins accuracy; YOLO-NAS wins latency, efficiency, and INT8.
 Modelos y detección
CNN vs Transformer, quantized: YOLO26-seg and RF-DETR-Seg race for instance masks on an Intel iGPU
Two opposite small segmentation models, a 2026-era CNN and a DETR transformer, both quantized to INT8 with NNCF and run on a laptop Intel iGPU. YOLO26-seg's forward pass is ~7.4× faster; RF-DETR-Seg keeps its masks more faithful under INT8 on the CPU, and its fully-quantized mask head breaks on the iGPU. The whole shootout, numbers first.