
rf-detr
3 posts · browse all tags
 Models & Detection
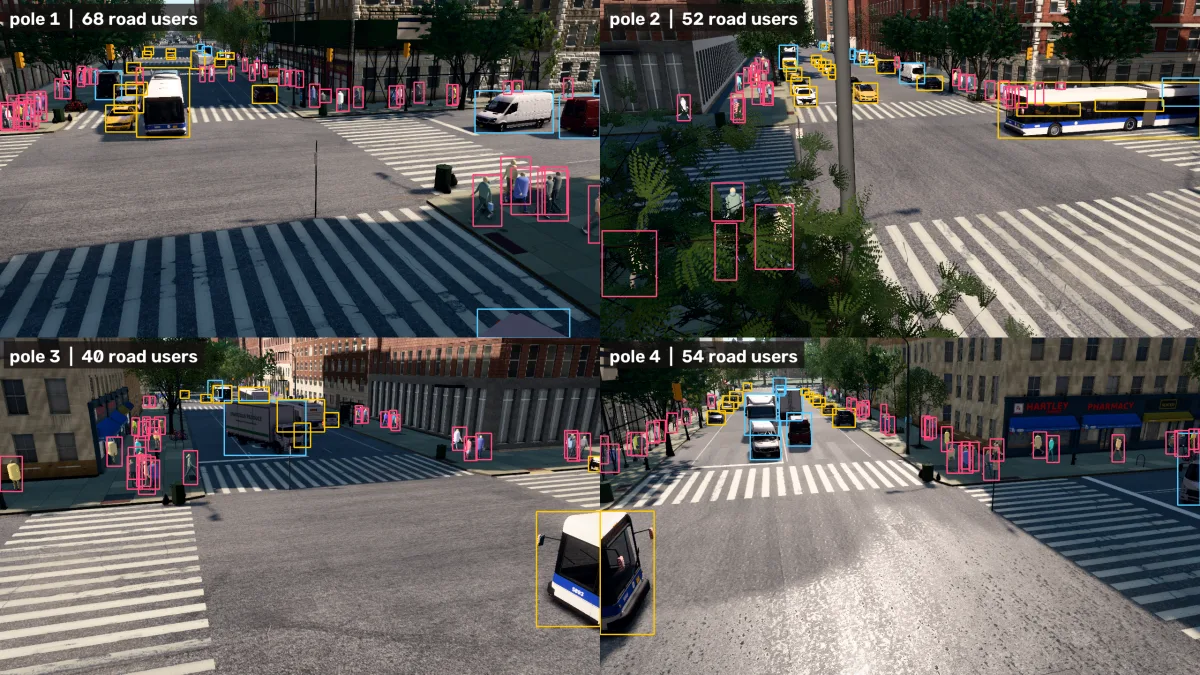
A Traffic Camera in a Simulated New York: Exact Labels at 0.75 s a Frame
A pole camera at a real Harlem junction, rendered by the Valdrada simulator on one desktop GPU: every car and pedestrian comes with its box, its mask, its depth and how much of it is hidden, at 0.75 s per labelled frame when four cameras share a capture. What it took to run headless on Linux, what a simulated label does and does not tell you, how far a COCO detector gets on it, and a recording format that lets the same code read a real camera later.
 Edge Deployment
RF-DETR vs YOLO-NAS: A Practical Benchmark for Edge Deployment: CPU, GPU, and Intel iGPU Compared
RF-DETR Nano vs YOLO-NAS-S on COCO across CPU, CUDA GPU, and Intel Iris Xe iGPU, across two resolutions, OpenVINO FP32/FP16/INT8, and a custom fine-tune, all under one consistent evaluation. RF-DETR wins accuracy; YOLO-NAS wins latency, efficiency, and INT8.
 Models & Detection
CNN vs Transformer, quantized: YOLO26-seg and RF-DETR-Seg race for instance masks on an Intel iGPU
Two opposite small segmentation models, a 2026-era CNN and a DETR transformer, both quantized to INT8 with NNCF and run on a laptop Intel iGPU. YOLO26-seg's forward pass is ~7.4× faster; RF-DETR-Seg keeps its masks more faithful under INT8 on the CPU, and its fully-quantized mask head breaks on the iGPU. The whole shootout, numbers first.